Historical Market Data CSV & JSON Format Explained
Before you run a download, it helps to know exactly what you're getting. Here is the column layout the MarketData Hub client writes for OHLC candles and for raw ticks, what the timestamp column actually contains, and the one line that turns it into a date in every common tool.
The two layouts at a glance
| File | Header row | One row is |
|---|---|---|
| Candles (1 second to monthly) | timestamp,open,high,low,close,volume | one bar, stamped with its opening time |
| Ticks | timestamp,askPrice,bidPrice,askVolume,bidVolume | one quote update |
Both are plain comma-separated text with a header row, oldest row first, a dot as the decimal separator and no thousands separators. The volume column is written when Include volumes is switched on in the app (the default) and left out entirely when it is off, so a five-column candle file is the same layout minus volume, not a different format.
OHLC candle CSV
timestamp,open,high,low,close,volume
1704153600000,1.10423,1.10489,1.10401,1.10455,184.3
1704153660000,1.10455,1.10472,1.10440,1.10461,121.0
Illustrative values, not market data.
open is the first price of the bar, high and low the extremes, close the last. Every candle is built from one side of the quote — bid or ask, chosen at download time — so a candle file carries no spread. Download both sides if your backtest needs one (the tick vs OHLC guide explains when it does).
Two details trip people up. First, the timestamp is the bar's opening time: the row stamped 00:01 covers 00:01:00 to 00:01:59.999. Second, the rows are not a complete grid. A minute in which the price never moved is left out rather than written as a flat bar, so on quiet nights and around holidays consecutive timestamps can be several minutes apart. If your code assumes row n+1 is exactly one interval after row n, reindex to a full grid first and decide deliberately how to fill the gaps.
Tick CSV — ask comes first
timestamp,askPrice,bidPrice,askVolume,bidVolume
1704153600123,1.10425,1.10423,2.0,1.5
1704153600318,1.10426,1.10424,1.2,1.0
Illustrative values, not market data.
Tick files record every quote update, so there is no open, high, low or close — just a millisecond timestamp with both sides of the quote and the volume available at each. Note the order: ask before bid. Most tools and tutorials assume bid first, and a positional import that maps column 2 to "bid" will quietly build a series whose spread is negative. Map tick columns by header name, never by position; a quick check is that askPrice − bidPrice should be positive on every row.
The timestamp column: epoch milliseconds, UTC
Timestamps are written as an integer: the number of milliseconds since 1 January 1970, 00:00 UTC. 1704153600000 is 2 January 2024, 00:00:00 UTC. That is deliberate. An integer cannot be misread by a locale (no 01/02 vs 02/01), carries no time zone to get wrong, keeps tick-level millisecond precision, and sorts correctly as a plain number. The cost is one conversion line wherever you open the file:
| Tool | Convert the timestamp column |
|---|---|
| Python · pandas | pd.to_datetime(df["timestamp"], unit="ms", utc=True) |
| Excel · Google Sheets | =A2/86400000+DATE(1970,1,1), then format the cell as yyyy-mm-dd hh:mm:ss |
| DuckDB | epoch_ms(timestamp) |
| R | as.POSIXct(df$timestamp / 1000, origin = "1970-01-01", tz = "UTC") |
| JavaScript | new Date(timestamp) |
All of them give UTC. Shift to a market's local time only at the very end, with a real time-zone database rather than a fixed offset: London, New York and Sydney all change their clocks, on different dates, so "UTC+1" is right for part of the year at most.
Load it into Python (pandas)
import pandas as pd

df = pd.read_csv("eurusd_m1_20240101_20250101.csv")
df["timestamp"] = pd.to_datetime(df["timestamp"], unit="ms", utc=True)
df = df.set_index("timestamp")
Do not reach for parse_dates=["timestamp"] here. It is the usual idiom for date strings, but on an integer column it leaves the values as integers without raising an error, and you end up with an index of large numbers. The pandas guide continues from this point: resampling, Backtrader, VectorBT.
Open it in Excel or Google Sheets
Import rather than double-click: Data → From Text/CSV in Excel, File → Import in Sheets. The timestamp arrives as a 13-digit number; add a column with =A2/86400000+DATE(1970,1,1) and give it a date-time format. Never save the file back to CSV from Excel. Excel displays long integers in scientific notation, and re-saving can write that rounded display (1.70415E+12) over the real value, which collapses thousands of distinct rows onto the same instant. The Excel and Sheets guide covers the row limits.
Query it with SQL (DuckDB)
SELECT epoch_ms(timestamp) AS ts, open, high, low, close
FROM read_csv_auto('eurusd_m1_20240101_20250101.csv')
LIMIT 5;
DuckDB reads the file in place with no import step; more recipes, including daily bars from minutes, are in the DuckDB guide.
File names and date ranges
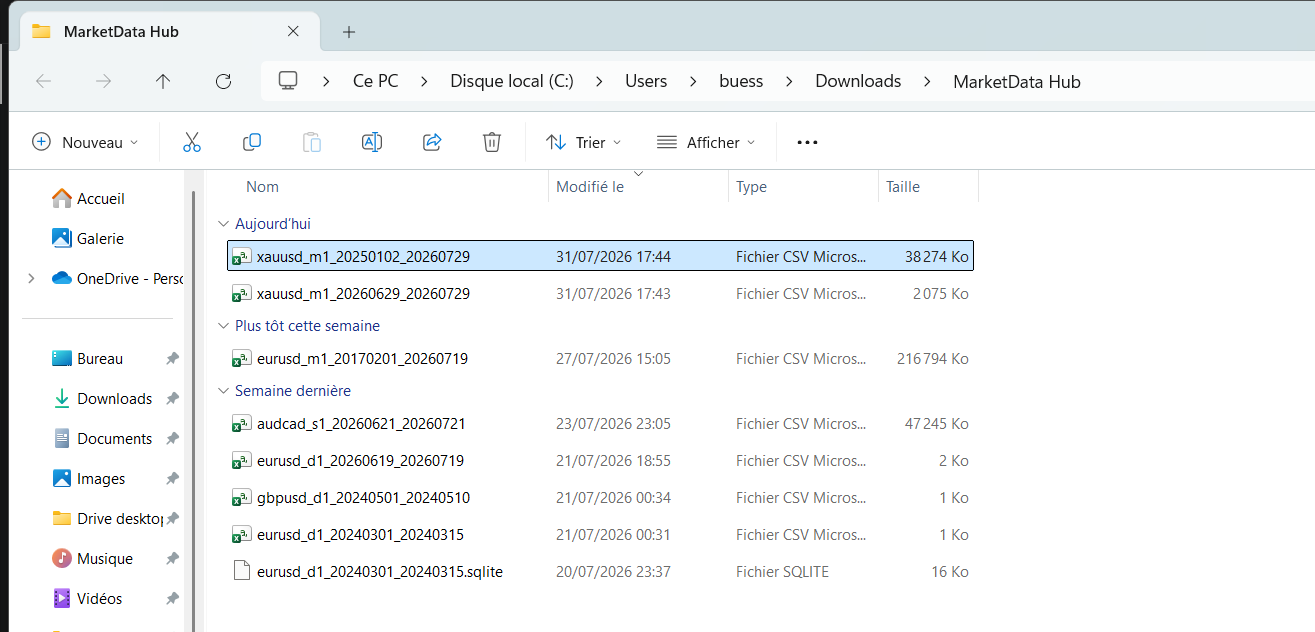
Files are named {instrument}_{timeframe}_{from}_{to}.csv — for example xauusd_m1_20240101_20250101.csv — with timeframes written tick, s1, m1, m5, m15, m30, h1, h4, d1 and mn1. The range is half-open: it includes the start date and stops just before the end date, so the file above holds every minute of 2024 and nothing from 1 January 2025. Two consecutive downloads that share a boundary date therefore never overlap and never leave a gap.
JSON format
[{"timestamp":1704153600000,"open":1.10423,"high":1.10489,"low":1.10401,"close":1.10455,"volume":184.3}, …]The JSON export is one array of objects with exactly the CSV's keys, numbers as numbers and the same epoch-millisecond timestamps. It loads with json.load or pd.read_json; convert the timestamp the same way as above.
The other formats (Pro licence)
- Parquet — the same columns, typed: the timestamp is an INT64 of epoch milliseconds and prices are doubles, so pandas, Polars and DuckDB read it without a parsing step.
- SQLite — a single database file with one table,
candlesorticks, plus a smallmetatable recording the instrument, timeframe and timestamp unit. - MetaTrader — a MetaTrader 4 history file (
.hst), the binary format the MT4 strategy tester reads directly. It holds bars only, so it is not offered for ticks. - NinjaTrader — NinjaTrader 8's import text: semicolon-separated, no header,
yyyyMMdd HHmmss;open;high;low;close;volumefor intraday bars andyyyyMMdd;…for daily.
Every tier, including the entry licence, reaches the same instruments and the same history; the formats are what differ. See what each tier changes, or open EUR/USD and gold to see the file sizes per timeframe.
Frequently asked questions
- What columns are in the CSV file?
- Candle files have timestamp, open, high, low, close and volume (volume is omitted when you switch volumes off). Tick files have timestamp, askPrice, bidPrice, askVolume and bidVolume, in that order: ask comes before bid. Every file has a header row and is sorted oldest first.
- What format is the timestamp in?
- An integer number of milliseconds since 1 January 1970 UTC (Unix epoch milliseconds). 1704153600000 is 2024-01-02 00:00:00 UTC. Convert it with pd.to_datetime(..., unit="ms", utc=True) in pandas, =A2/86400000+DATE(1970,1,1) in Excel or Google Sheets, or epoch_ms() in DuckDB.
- Is a candle timestamp the open or the close of the bar?
- The open. The row stamped 14:00 in an hourly file covers 14:00:00 up to, but not including, 15:00:00, all in UTC.
- Why are some minutes missing from a 1-minute file?
- Minutes in which the price did not move are left out rather than written as flat bars, so quiet periods and holidays show up as gaps between timestamps. Weekends are absent for markets that close. Reindex to a full grid in your own code if you need one row per interval.
- Is the data bid or ask price?
- For candles you choose the side at download time, and each file is one side. Tick files always carry both bid and ask on every row.
Related markets
- Commodities – Energy historical data · 4 instruments
- Commodities – Metals historical data · 3 instruments
- Commodities – Agriculture historical data · 6 instruments
- The full catalogue · all 265 instruments